
High-Speed Architecture
Efficient 6B Parameter Model
Delivers sub-second inference latency on enterprise GPUs and fits comfortably on 16GB consumer cards using only 8 steps (NFEs).
Advanced Capabilities
Bilingual Text & Photorealism
Generates stunning photorealistic images with distinct capabilities in rendering accurate English and Chinese text directly within the visual.
Specialized Variants
Turbo, Base, and Edit Modes
Three tailored solutions in one family: a distilled speed model, a foundation for fine-tuning, and a dedicated variant for natural language image editing.
Choose Your Checkpoint: Turbo, Base, vs. Edit
A side-by-side comparison of the Z-Image family. Explore the technical differences between our distilled high-speed inference model, the open foundation for fine-tuning, and the specialized variant for instruction-based editing.
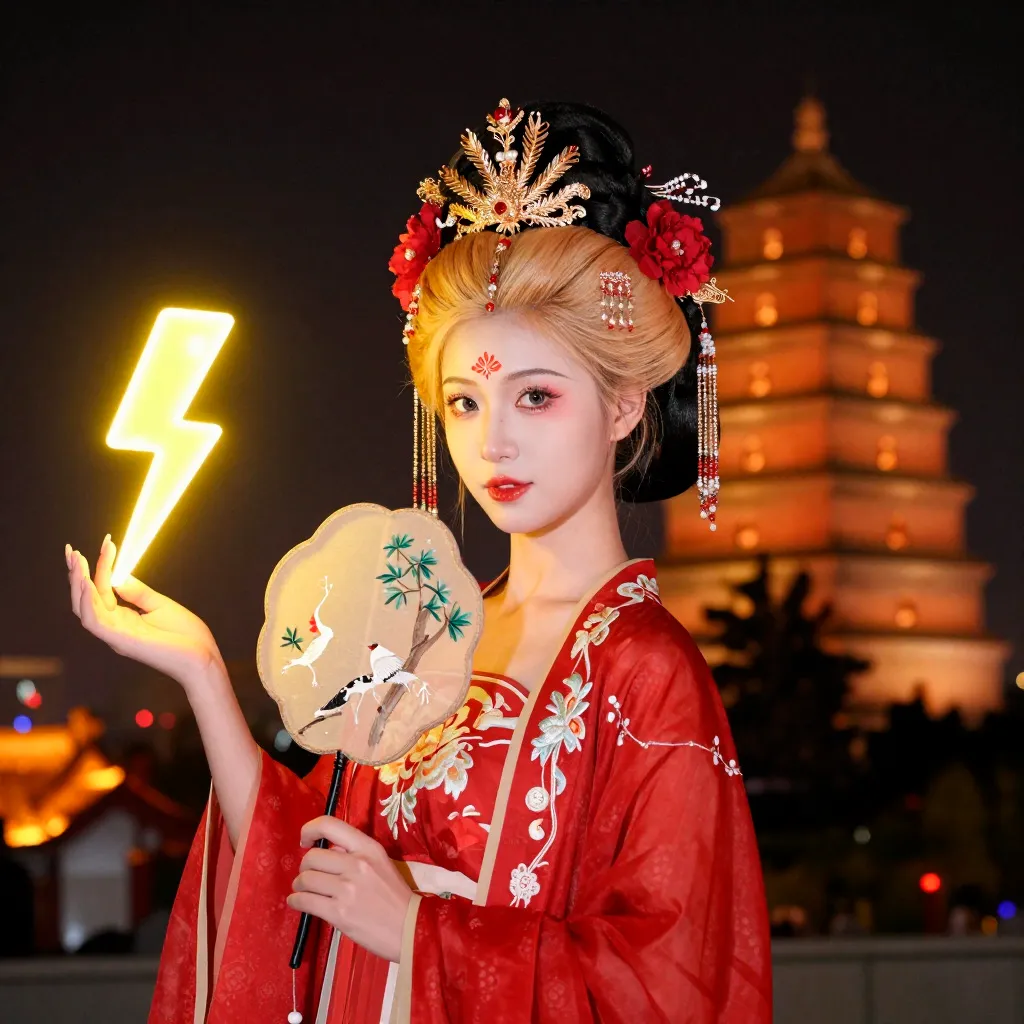
Z-Image-Turbo
A distilled version of Z-Image that matches or exceeds leading competitors with only 8 NFEs (Number of Function Evaluations). It offers sub-second inference latency on enterprise-grade H800 GPUs and fits comfortably within 16G VRAM consumer devices.
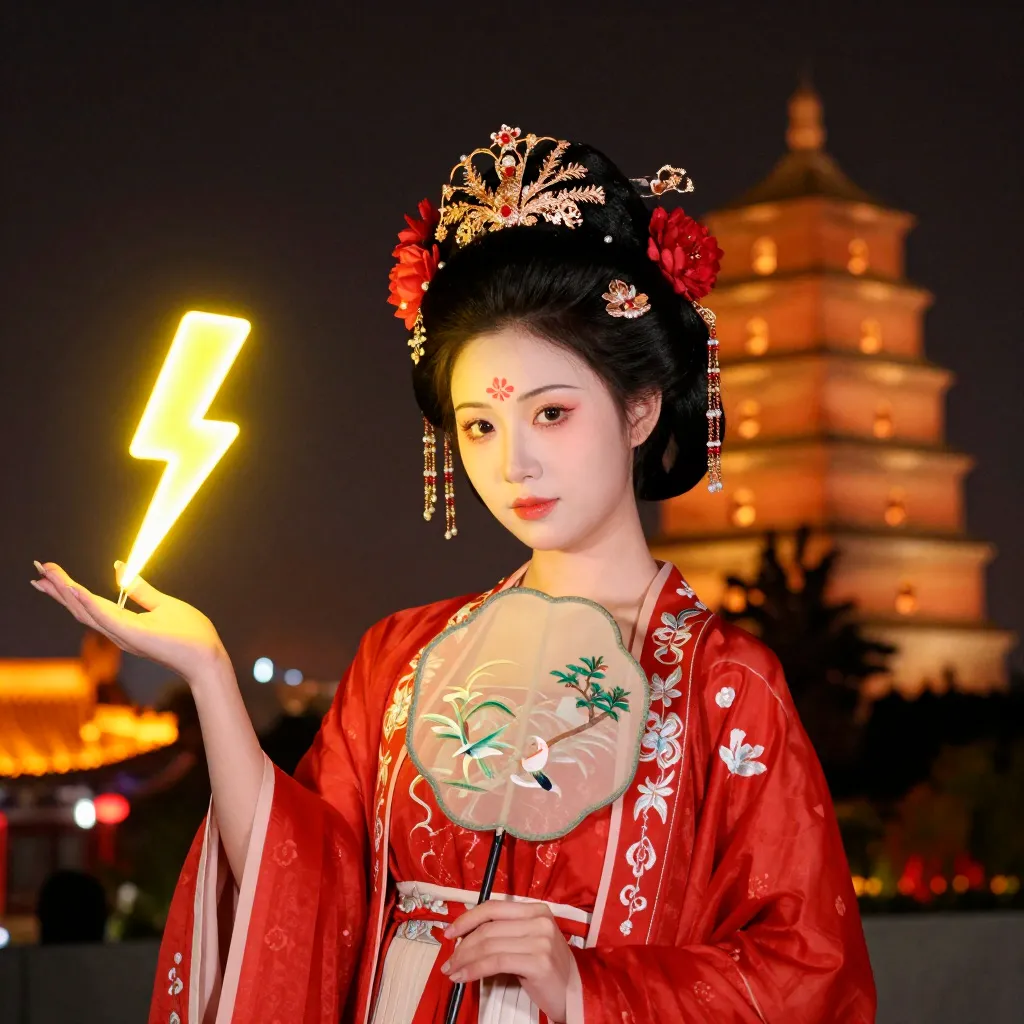
Z-Image-Base
The non-distilled foundation model. By releasing this checkpoint, we aim to unlock the full potential for community-driven fine-tuning and custom development.
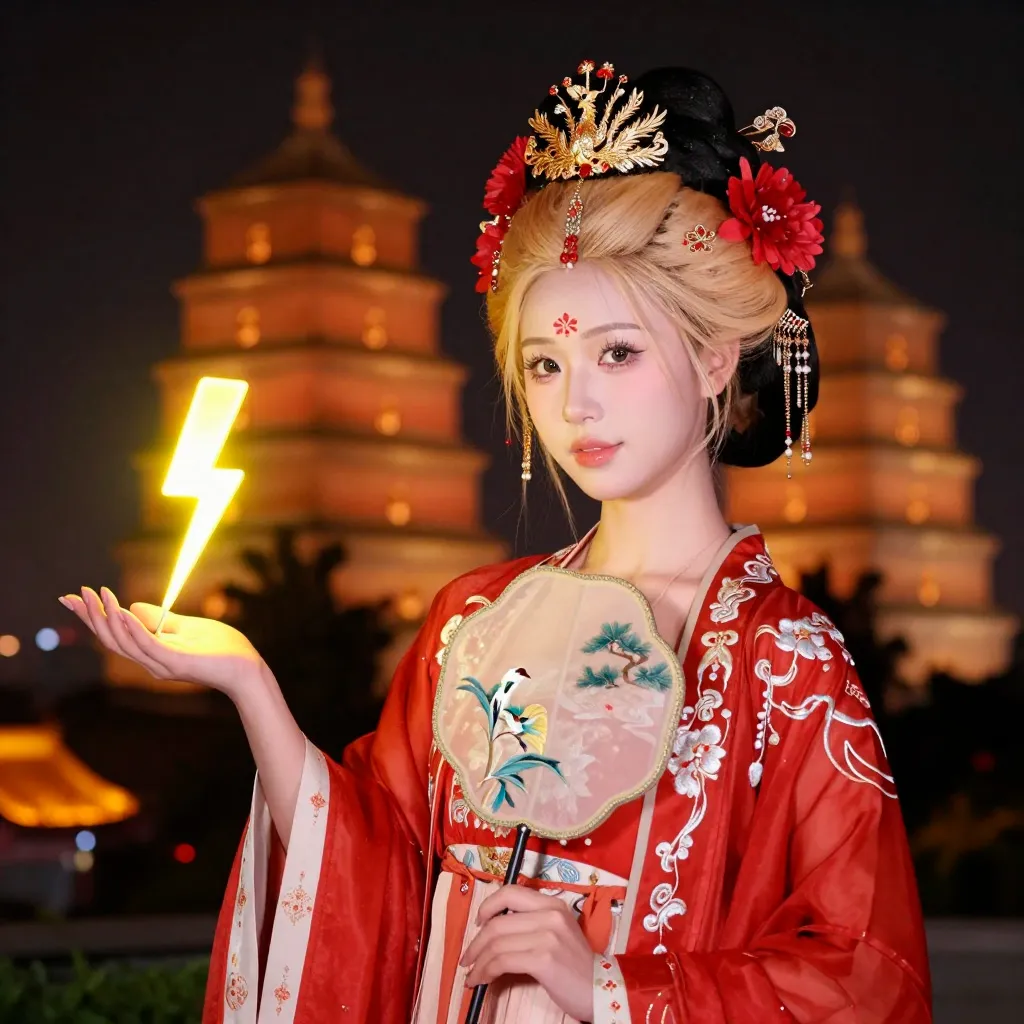
Z-Image-Edit
A variant fine-tuned on Z-Image specifically for image editing tasks. It supports creative image-to-image generation with impressive instruction-following capabilities
The New KING of LOCAL Image Models
See how this lightning-fast, locally-run AI image generator stacks up. Bijan Bowen tests Z-Image Turbo, a 6-billion parameter model, using diverse prompts. Discover if this open-source model truly reigns supreme.
Real-World Applications of Z-Image
Powering Chatbots & Live Generators
Leverage Z-Image-Turbo to integrate image generation into consumer-facing apps or chatbots. With sub-second inference latency and low memory requirements (16GB VRAM).
You can deliver instant visual responses to user queries without the need for massive server clusters.
Creating Bilingual Visuals with Perfect Text
Use Z-Image-Turbo for designing posters, social media banners, and e-commerce visuals that require embedded text. Its ability to accurately render both English and Chinese characters ensures your typography is legible and perfectly integrated into photorealistic scenes.
Streamlining Edits with Natural Language
Deploy Z-Image-Edit for tasks that require modifying existing assets rather than starting from scratch. whether changing a background, swapping an object, or altering the lighting, designers can execute precise edits using simple text instructions, significantly reducing manual photoshop time.
Training Custom Models on Proprietary Data
Utilize Z-Image-Base when you need a model tailored to a specific style, brand identity, or medical/scientific dataset. As a non-distilled foundation, it serves as the perfect starting point for community fine-tuning, allowing developers to build niche tools on a powerful 6B parameter architecture.
Frequently Asked Questions (FAQ)
Z-Image is designed to be accessible. It fits comfortably within 16GB VRAM, making it compatible with many high-end consumer graphics cards (e.g., NVIDIA RTX 3090/4080/4090).
Z-Image-Turbo is capable of sub-second inference latency when running on enterprise-grade hardware like H800 GPUs. On consumer hardware, it remains exceptionally fast due to its optimized 8-step (NFE) generation process.
Yes. Z-Image excels at bilingual text rendering, capable of accurately generating legible text in both English and Chinese within images, making it ideal for poster design and marketing materials.
This refers to how well the model listens to your prompt. Z-Image-Turbo and Edit are tuned for robust instruction adherence, meaning they faithfully include the specific details, styles, and text strings you ask for, rather than ignoring parts of the prompt.
Z-Image stands out due to its balance of size and speed. With 6B parameters, it offers high fidelity, yet the Turbo variant requires only 8 Function Evaluations (NFEs), allowing for sub-second inference on high-end hardware and efficient performance on consumer GPUs.